RRULE in Practice: Parsing, Validating, and Quarantining Recurrence Rules
iCalendar RRULE looks like a solved problem until INTERVAL=0 hangs your sweep, BYHOUR means the wrong hour across timezones, and legacy rows encode their whole schedule in one string. A field guide to doing it safely.
 Teo ParashkevovPublished6 min read
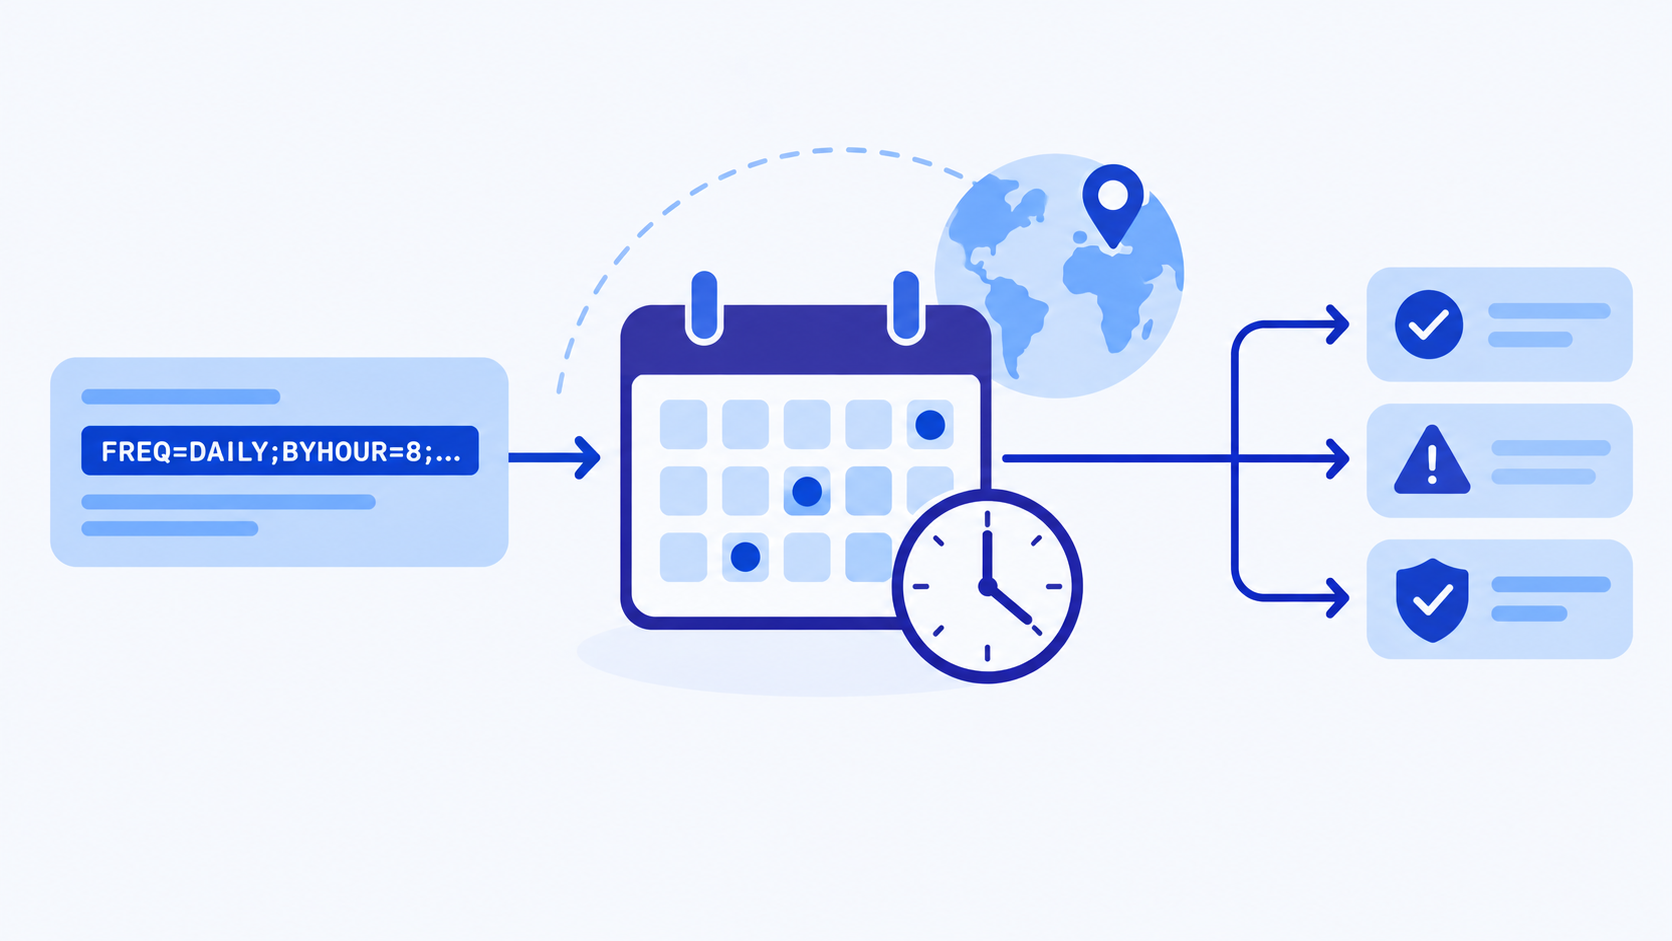
RRULE — the iCalendar recurrence-rule string — is one of those formats that is 80% trivial and 20% landmine. Most rules are FREQ=WEEKLY;BYDAY=MO. But the edge cases are genuinely dangerous: a single malformed rule can hang a scheduling loop forever, a timezone mishandled shifts every occurrence by three hours, and a legacy data scheme can silently change what “daily” means. This post collects the failure modes I’ve hit and the defenses that work against each.
A quick tour of the format
An RRULE describes recurrence compactly:
FREQ=DAILY;INTERVAL=2;COUNT=10         # every other day, 10 times
FREQ=WEEKLY;BYDAY=MO,WE,FR;UNTIL=20240101T000000Z
FREQ=MONTHLY;BYMONTHDAY=15             # the 15th of every month
The string pairs with a DTSTART (first occurrence, carries the timezone) and optionally UNTIL (hard cutoff). Python’s dateutil.rrule.rrulestr() parses the string into a lazy generator of datetimes — which is exactly where the first landmine lives.
Landmine 1: the infinite rule that never raises
INTERVAL=0 produces a rule whose generator yields DTSTART forever. Not “a lot of times” — forever, in tight loop. The first time most teams notice is when their scheduler stops making progress and every query looks green, because a hang never raises. There is no exception to catch; the sweep thread just stops existing as far as the rest of the system is concerned.
The defense is a pre-check, not a try/except — inspect the parsed rule’s interval before iterating:
def quarantine_reason(rule) -> str | None:
    if getattr(rule, "_interval", 1) <= 0:
        return "INTERVAL must be positive"
    return None
Rules that fail the pre-check don’t get iterated at all; the definition is paused (not completed — an exhausted rule is finished, but an invalid one should be recoverable by an edit), a human is surfaced the reason, and the sweep moves on. The general principle deserves emphasis: you cannot try/except your way out of a non-raising failure. Some conditions (hangs, livelocks) can only be caught by checking the input before executing it.
Landmine 2: BYHOUR is wall-clock, and wall-clock has a timezone
Say a user in Sofia wants a daily 08:00 report. If you parse the rule with a naive DTSTART in UTC, BYHOUR=8 fires at 08:00 UTC — 10:00 or 11:00 Sofia time depending on DST, drifting twice a year and wrong every day in between. The rule doesn’t carry a timezone; DTSTART must be aware, anchored in the user’s zone:
dtstart = datetime(2024, 1, 1, 8, 0, tzinfo=ZoneInfo(tz_name))
rule = rrulestr(rrule_string, dtstart=dtstart)
This sounds obvious written down. It is also the single most common recurrence bug in production systems, because tests pass: a test suite running in UTC against UTC-anchored rules is perfectly self-consistent and perfectly wrong for every real user.
A related subtlety: UNTIL appearing in naive form (20240101T000000 with no Z) makes some parsers raise, and a raise deep in a scheduler loop can silently swallow the whole definition. Best-effort normalizing naive UNTIL to UTC — rewriting the stamp to carry the intended wall-clock meaning — keeps old rows parseable without changing what the user meant.
Landmine 3: one function cannot serve two masters
The scheduler wants lenient parsing: a malformed rule should return “no schedule” (skip this definition, log, continue the tick — one bad row must not kill the loop). Form UI wants strict validation: a malformed rule should raise a detailed error naming the offending field, refuse impossible combinations (BYMONTHDAY=30 with BYMONTH=2 — February 30th), and reject constructs you don’t support (DTSTART, RDATE, EXDATE, EXRULE embedded in user input — those belong to you, the system, not to the user).
These are different functions. Fusing them produces the worst of both: either your scheduler throws on bad data, or your users get “saved!” for rules that silently never fire. Keep them as an explicit pair:
parse_rrule(text, tz_name) -> Rule | None      # lenient, cached, scheduler-side
validate_rrule(text, tz_name) -> Rule           # strict, raising, form-side
The strict validator should validate against a fixed anchor date (say 2000-01-01), not now(). Validation results must not change with the calendar; “this rule is well-formed” should be a stable predicate so tests and form behavior are reproducible forever.
Two more production details:
- The lenient parser is hot; cache it — an LRU bounded by a few hundred entries, with the timezone in the cache key. Two zones must never share a parsed rule; that’s a recurrence of Landmine 2 in cache form. And the strict validator must not touch that cache, or form traffic evicts the scheduler’s hot entries.
- Unknown timezone is an error, not a fallback. A preview that silently substitutes UTC shows the user the wrong times with total confidence. Raise
UnknownTimezone; let the form say so.
Landmine 4: legacy rows that encode the schedule type inside the rule
Over a system’s life, the data model changes. Suppose generation-1 rows encoded everything in the RRULE string — a daily rule was how you said “recurring”, and one-shot surveys were modeled as COUNT=1. Generation-2 introduces explicit schedule_type (once | recurring | always_on) plus separate window fields, and RRULE now carries only the recurrence detail.
Old rows don’t migrate themselves. Reading them needs a resolution function — one place that interprets ambiguous data:
resolve(schedule_type, window_start, window_end, rrule):
    # explicit, backfilled rows
    if type == always_on and no rrule:  → always_on
    if type == once:                    → once (window from fields or COUNT=1 rule)
    if type == recurring and window:    → recurring
    # derived fallback for legacy rrule-only rows
    if no rrule:                        → always_on
    if COUNT == 1:                      → once
    else:                               → recurring (window from DTSTART/UNTIL)
The case that earns its keep: once must never fall back to always_on just because its window is missing. A completed one-time survey that resolves to “always on” gets re-presented to users as perpetually fillable — a real-world bug class that only shows up months later, when someone notices a concluded survey collecting new sessions. The one-shot survey has a special protected status precisely because the failure mode is silent and the blast radius is data corruption (a “completed” instrument accepting answers forever).
And the flip side matters too: when a once derives its window from a rule, only a COUNT=1 rule may contribute. A recurring rule’s DTSTART/UNTIL bound the series, not any single occurrence — using them to window a one-shot is a category error that produces intervals spanning months.
Putting it together: occurrence intervals
Given a resolved schedule, a common question is “which occurrence did this session belong to?” The robust formulation is half-open intervals between consecutive occurrences, clipped to the window:
occurrences = sorted(rule.between(lower, upper, inc=True))
intervals = [(occ[i], occ[i+1]) for i in range(len(occ)-1)]
# final interval capped at window_end (or display end)
# drop degenerate intervals where end <= start
Then a session “counts” for an occurrence iff its completion timestamp falls in [start, end). Half-open intervals make boundary cases unambiguous: exactly one interval contains any given instant; back-to-back occurrences don’t double-count.
Performance note: expanding a daily rule that started in 2015 over its full history costs real milliseconds per row. When a derived statistic (like “did every assignee attend every occurrence?”) can be answered by a cheap check first — “someone has zero sessions at all” already proves incompleteness — short-circuit before the expensive expansion. Most rows in a real dataset take the cheap path.
Takeaways
- Hangs don’t raise. Guard
INTERVAL=0-style inputs with pre-execution checks; you cannot catch a hang. - Anchor
DTSTARTin the user’s zone, orBYHOURmeans the wrong hour for everyone outside UTC. Cache with the zone in the key. - Lenient scheduler parsing and strict form validation are different functions with different failure postures — keep them apart, anchor validation on a fixed date, and treat unknown timezones as errors.
- Data-model migrations need a single resolver, and terminal states (
once,archived) must be protected from optimistic fallback that would resurrect them. - Use half-open intervals for occurrence attribution, and short-circuit expensive rule expansions when a cheaper predicate settles the question.
RRULE is a solved problem the way chess is a solved problem: the rules fit on a page, and the interesting part is everything that happens when real opponents — malformed input, timezones, legacy data — sit down across from you.